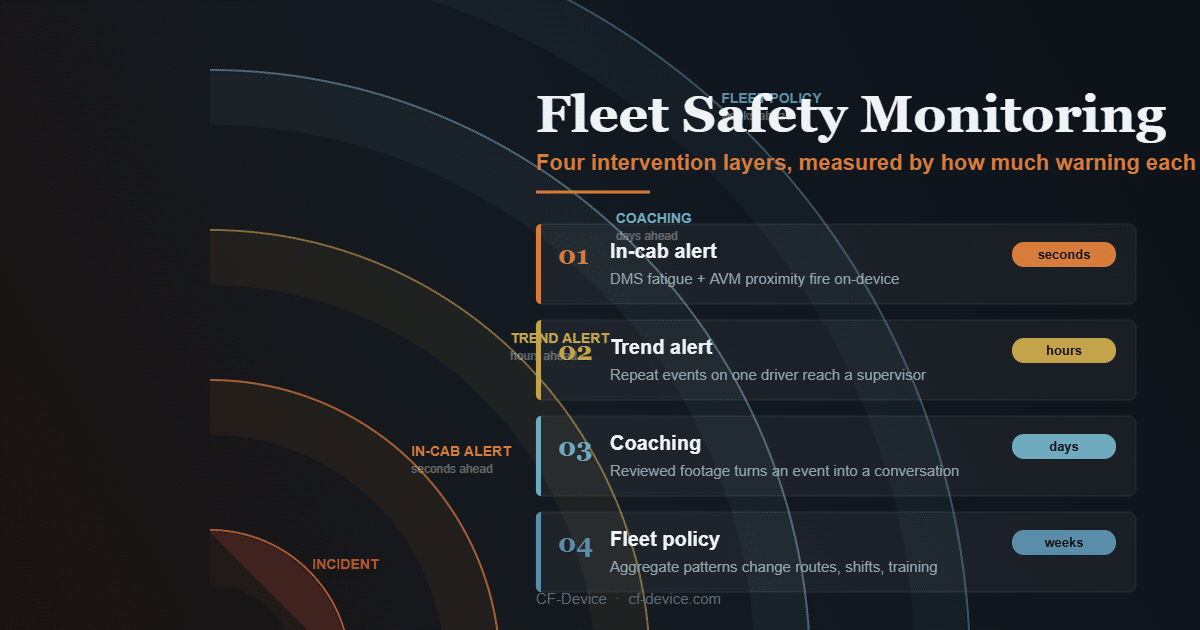
Fleet safety monitoring is usually bought as a product — a camera, a platform, a subscription. It works better understood as four separate intervention layers, distinguished by one thing: how far ahead of an incident each one can act. A layer that arrives seconds early prevents; a layer that arrives weeks later improves. Both are necessary, and neither substitutes for the other. CF-Device’s terminals carry the first layer in the cab and capture the events that the other three layers depend on.
TL;DR
- Four layers: in-cab alert (seconds), trend alert (hours), coaching (days), fleet policy (weeks)
- Only the first layer prevents incidents — it has to run on the terminal, not in the cloud
- The other three depend on events being captured reliably first, including in dead zones
- Programmes fail most often at layer two: alerts nobody owns reviewing
- False-alert rate matters more than detection rate — ignored alerts protect nobody
Fleet Safety Monitoring, Layer One: The In-Cab Alert
This is the only layer that can change an outcome rather than record one. In-cab alerts are the whole point: a driver’s eyes closing, a pedestrian entering a blind zone behind a reversing loader — the useful response window is under a second, which rules out anything that involves sending a video frame to a server and waiting for a verdict.
In short: prevention requires on-device inference; everything sent to the cloud arrives too late to prevent and can only document.
Two systems do this work. DMS driver monitoring watches the driver — eye closure, head position, phone use, smoking — and AVM 360° surround view watches the space around the vehicle. Both run as continuous vision analysis on the terminal’s own processor, which is why NPU capacity rather than screen size is the constraining spec, as covered in what is an NPU. Where the vehicle is a forklift, the same layer is set out in forklift safety system: pedestrian detection, speed control and driver monitoring.
Which CF-Device Models Carry the In-Cab Layer
Not every model lists both systems. CF-Device’s datasheets list CF AVM 360° on the VCM M10, V12 PRO, V10-2, V7-2, V7A-2, V12-2, S10-2, S10-2 PRO, S10-2 PLUS and TANK V2, with camera-input counts that differ by model. DMS is listed on the VCM M10, which also lists forward collision warning; for the other models the DMS and collision-warning entries are not on the datasheet, so confirm them before specifying a unit for a driver-monitoring programme. The VCM M10 is the model that lists AVM 360°, DMS and FCW together, and its NPU headroom is what allows them to share one terminal.
Layer Two: The Trend Alert
A single fatigue event on a long shift is normal human variance. The same driver triggering fatigue alerts on four consecutive afternoons is a scheduling problem, and no individual alert reveals it. Layer two is pattern recognition across events — and it’s where most safety programmes quietly stop working.
The failure isn’t technical. It’s that nobody owns the review. Alerts land in a dashboard, the dashboard produces more entries than anyone reads, and within a few weeks the queue is treated as noise. A fleet safety program without a named person, a fixed review cadence, and a defined threshold for escalation has layer one and nothing above it.
Layer Three: Coaching
Coaching converts a recorded event into a changed habit, and it’s the layer where the programme’s framing matters most. Driver behavior monitoring introduced as surveillance produces defensive drivers who learn where the camera’s limits are. The same hardware introduced as evidence that protects the driver in a disputed incident produces cooperation.
That difference isn’t cosmetic — it decides whether drivers work with the system or around it, and a fleet that gets this wrong ends up paying for hardware whose value is actively undermined by the people operating it.
Layer Four: Fleet Policy
Aggregate data answers questions individual events cannot. If fatigue alerts cluster in the final ninety minutes of a particular shift pattern, the fix is the roster, not the drivers. If proximity warnings concentrate at one depot’s loading bay, the fix is the site layout. This layer changes the conditions that generate events rather than responding to them. Driver safety monitoring at this level is a fleet-wide question, not a per-driver one.
It’s also the layer that produces the reporting insurers and regulators ask for — and the one that requires the longest data history before it says anything reliable.
What Runs on the Terminal, What Runs in the Office
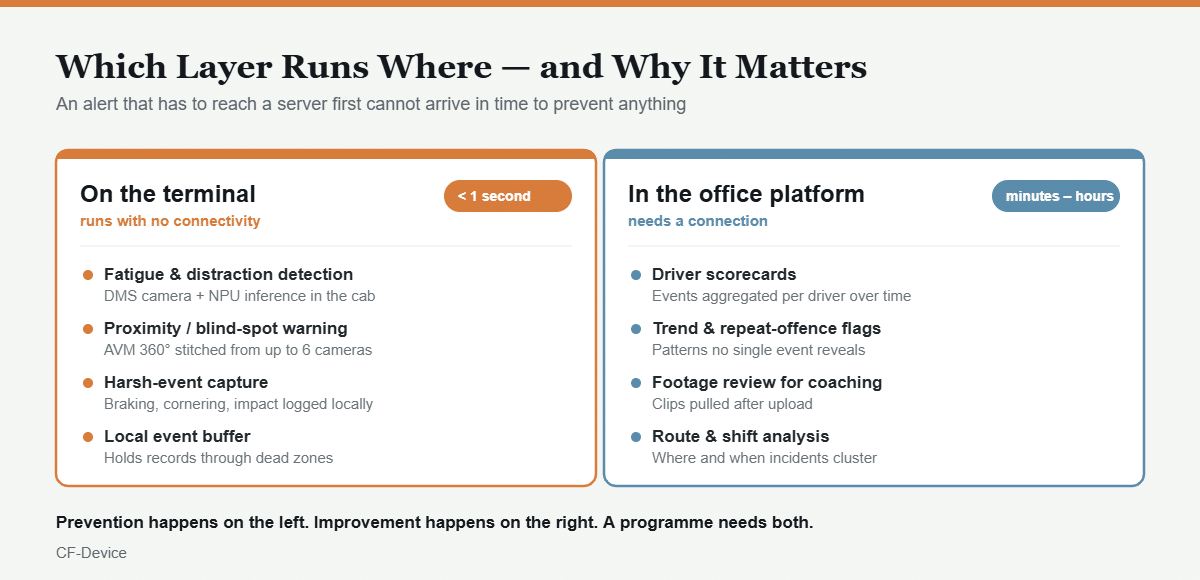
The split isn’t a design preference — it follows from latency. Anything that must act inside a second lives on the terminal. Anything that needs data from many vehicles over time lives in the platform. Getting this backwards is the most expensive mistake in the category: a system marketed on cloud AI sophistication, whose alerts arrive after the moment they were meant to prevent.
The dependency runs one way. Layers two through four consume what layer one captured — so if the terminal drops events in low-coverage areas instead of buffering them locally, the office layers are analysing an incomplete record without knowing it. Local logging with sync-on-reconnect, where the terminal and platform support it, is what keeps the upper layers honest, the same constraint discussed in fleet vehicle GPS tracking systems.
Why False Alerts Decide Whether Any of This Works
Vendors compete on detection rate. Fleets should evaluate on false-alert rate, because the failure mode of an over-sensitive system isn’t harmless — it’s total. A DMS that flags a driver checking a mirror teaches that driver to disregard the alert tone within a week, at which point the genuine alert is disregarded too.
Worth asking in a trial: how many alerts per driver per shift does this generate in our operating conditions, and how many of those were real? A pilot on real routes answers this; a vendor demo does not.
An Illustrative Deployment Example
Picture a regional haulier that fits DMS and AVM across 60 trucks and sees no measurable change in incident rate for five months. The hardware is working — layer one is firing correctly and events are logging. Nothing above it exists: no owner for the alert queue, no review cadence, no coaching process.
The change that produces results isn’t hardware. A depot supervisor is given a fifteen-minute daily review of flagged events and authority to adjust a driver’s next shift. Same terminals, same detection, three layers instead of one — and the passenger-safety version of this pattern is covered in smart transportation: DMS and AVM 360°.
Building the Programme in Order
- Confirm on-device processing — alerts must fire without connectivity, or layer one doesn’t exist
- Pilot for false-alert rate — on real routes, counting alerts per driver per shift
- Name the reviewer before rollout — layer two needs an owner, not a dashboard
- Set the coaching frame — protection, not surveillance, decided before drivers see the hardware
- Wait for enough data — policy conclusions need months, not weeks
Keeping detection models and firmware current across a deployed fleet is a separate ongoing requirement — handled through the management layer described in MDM remote device management, and running alongside the other systems on the same terminal as set out in One Tablet, Four Systems. The hardware requirements behind all of it are in our rugged vehicle tablet hardware guide.
Common Questions
Can I run fleet safety monitoring with just a dash camera?
A dash camera records for after-the-fact review — that’s layers three and four only. Prevention needs on-device analysis capable of alerting the driver in the moment.
Do drivers usually accept in-cab monitoring?
Acceptance tracks how it’s introduced. Framed as evidence protecting the driver in disputed incidents, resistance is limited; framed as surveillance, drivers work around it.
How long before a safety programme shows measurable results?
Layer one changes behaviour immediately. Measurable incident-rate change usually needs several months, and only if layers two and three are actually operating.
Does safety monitoring work in areas with no cellular coverage?
The alerting layer does, since it runs locally. Events buffer on the terminal and upload on reconnect, so the office layers stay complete provided the terminal and platform support local logging.
Can one terminal run DMS and AVM at the same time?
Yes, given sufficient NPU headroom — but confirm it against both features running concurrently, not each tested alone, since they share the same processing budget. Among CF-Device models, the VCM M10 is the one whose datasheet lists both DMS and AVM 360°; ask for a concurrent test before specifying any other model for both.
Interested in specs or a quote? Contact our team to discuss safety monitoring terminals for your fleet.